To block AI crawlers, add rules to your site’s robots.txt file that disallow the specific AI user agents you want to keep out, such as GPTBot or ClaudeBot, and use firewall or bot management rules for crawlers that do not follow robots.txt. The important decision is which ones to block. Most AI companies now run separate bots for model training, for search indexing and for fetching pages when a user asks. If you block AI crawlers without separating those roles, you can disappear from AI answers that would otherwise cite and link to you.
This guide lists the main AI crawlers, explains how to block AI crawlers selectively, and helps you decide what to allow.
Why sites block AI crawlers
Publishers and businesses block AI crawlers for a few reasons:
- They do not want their content used to train AI models without permission or payment.
- Heavy crawling adds server load and bandwidth costs.
- They want to protect paid or proprietary content.
- They are negotiating licensing deals and want bargaining power.
Those are reasonable goals. The tradeoff is visibility. AI assistants increasingly answer questions with citations and links. If their search crawlers cannot read your pages, they cannot cite you, and a competitor gets mentioned instead.
The three kinds of AI crawlers
Most major AI companies now separate their bots by purpose:
- Training crawlers collect content that may be used to train future models.
- Search crawlers index pages so the assistant can find and cite them when answering questions.
- User-triggered fetchers retrieve a page when a person using the assistant asks about it or shares a link.
Blocking a training crawler does not stop the search crawler, and the reverse is also true. That gives you fine-grained control, but only if you name the right bots.
Main AI crawlers and what they do
| Company | User agent | Purpose |
|---|---|---|
| OpenAI | GPTBot | Collects content that may be used to train models |
| OpenAI | OAI-SearchBot | Indexes pages for ChatGPT search results and citations |
| OpenAI | ChatGPT-User | Fetches pages for user actions in ChatGPT |
| Anthropic | ClaudeBot | Collects content that may be used to train models |
| Anthropic | Claude-SearchBot | Indexes content to improve Claude’s search results |
| Anthropic | Claude-User | Fetches pages when a Claude user asks a question |
| Perplexity | PerplexityBot | Indexes pages for Perplexity answers |
| Perplexity | Perplexity-User | Fetches pages for user requests |
| Google-Extended | A control token for whether Google may use your content for Gemini models and grounding | |
| Apple | Applebot-Extended | A control token for Apple’s use of content in AI training |
| Common Crawl | CCBot | Builds a public web archive that many AI developers use |
Companies add and rename bots over time, so check each company’s own documentation before you edit robots.txt. OpenAI documents its crawlers in its bots overview, and Anthropic explains its crawlers in its help center.
How to block AI crawlers with robots.txt
Robots.txt sits at the root of your domain, for example example.com/robots.txt. Each rule names a user agent and the paths it may not crawl. To block a single crawler from your whole site:
User-agent: GPTBot
Disallow: /
To block AI crawlers used for training while keeping search crawlers allowed, list each training bot separately:
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: Google-Extended
Disallow: /

User-agent: Applebot-Extended
Disallow: /

User-agent: CCBot
Disallow: /

User-agent: OAI-SearchBot
Allow: /

User-agent: Claude-SearchBot
Allow: /

User-agent: PerplexityBot
Allow: /
You can also block AI crawlers from specific folders only, such as a members area, by using a path instead of a slash. Apply rules on every subdomain that serves content, since each has its own robots.txt. Changes are not instant. OpenAI, for example, notes that its search systems can take around a day to reflect a robots.txt update.
What robots.txt cannot do
Robots.txt is a request, not a lock. Reputable crawlers follow it, but nothing forces a bot to comply. Some user-triggered fetchers are treated differently. OpenAI says robots.txt rules may not apply to ChatGPT-User because a person initiated the action. Anthropic says its bots, including Claude-User, respect robots.txt. Behavior varies by company, so read each one’s documentation.
Robots.txt also does not remove content already collected, and it does not stop other sites from quoting or summarizing your pages.
How to block AI crawlers at the firewall
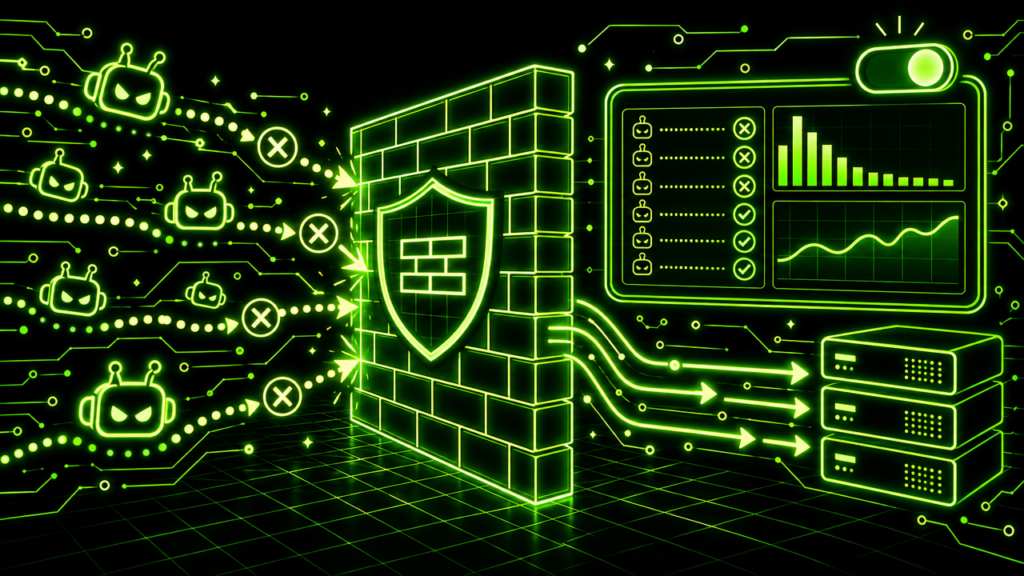
For stronger control, use a web application firewall or your CDN’s bot management. Many CDN and security providers now offer settings to block AI crawlers in one step, rules based on user agent or verified bot lists, and rate limiting for heavy crawlers. Some providers can verify bots against the IP ranges that AI companies publish, which helps catch impostors using a real bot’s name.
Be careful with broad firewall rules. Blocking by IP range can catch the wrong traffic, and some AI companies note that blocking their IPs can prevent their bots from reading your robots.txt at all, which makes your preferences harder to honor. Start with robots.txt, then add firewall rules for bots that ignore it or crawl too aggressively.
Should you block AI crawlers?
It depends on how your business makes money from content.
- Publishers that earn from ad impressions or subscriptions may want to block AI crawlers used for training, and think carefully about search crawlers, since AI answers can reduce clicks.
- Businesses that sell products or services usually benefit from being cited. For them, blocking training crawlers is a reasonable choice, but blocking search crawlers or user fetchers mostly removes them from AI recommendations.
- Sites with private or paid content should block AI crawlers from those sections and use login protection, since robots.txt alone does not secure anything.
A common middle path is to block AI crawlers used for training and allow those used for search and user requests. That keeps your pages eligible for citations and links in AI answers while opting out of future training where the company offers that choice. Our guide to GPTBot covers OpenAI’s crawlers in more depth.
Three sample robots.txt policies
Most sites end up with one of three approaches. Pick the one that fits your goals, then adjust the bot list to match current documentation.
Maximum visibility
Allow all reputable AI crawlers. This suits businesses that want to be recommended and cited as widely as possible and are comfortable with their public content being used for training. Your robots.txt does not need AI-specific rules at all, though listing the main search crawlers with Allow makes your intent clear.
Opt out of training, stay in search
Block AI crawlers that collect training data, such as GPTBot, ClaudeBot, Google-Extended, Applebot-Extended and CCBot, while allowing search crawlers and user fetchers such as OAI-SearchBot, Claude-SearchBot, Claude-User, PerplexityBot and Perplexity-User. This is the most common middle path for businesses and many publishers.
Opt out of everything you can
Block AI crawlers of every kind, including search and user agents, and add firewall rules for bots that ignore robots.txt. This suits sites whose business depends on readers visiting the site directly, or that have licensing concerns. Expect to disappear from many AI answers as a result.
How to block AI crawlers on common platforms
Where you edit robots.txt depends on your platform:
- WordPress. Many SEO plugins include a robots.txt editor in their settings. You can also upload a physical robots.txt file to the site root, which overrides the virtual one WordPress generates.
- Shopify. Stores can customize robots.txt through a theme template file, which lets you add rules for specific user agents.
- Website builders. Some hosted builders limit robots.txt editing. Check their help documentation, and use your CDN or domain provider’s bot settings if direct editing is not available.
- Custom sites. Edit the robots.txt file in your web root, or configure your framework to serve it.
After any change, open yoursite.com/robots.txt in a browser to confirm the live file shows your new rules.
How to verify that a bot is real
Anyone can put “GPTBot” or “ClaudeBot” in a user agent string. When you block AI crawlers or allow them, you are trusting that the name is honest. Several AI companies publish the IP ranges their crawlers use, so you or your security provider can confirm that a request claiming to be a known bot comes from the right network. Many CDN and firewall services do this automatically through verified bot lists. Unverified traffic using a well-known bot name is a common sign of scrapers trying to blend in.
Should publishers block AI crawlers?
Publishers face the hardest version of this choice. AI answers can summarize articles and reduce clicks, which hurts ad and subscription revenue. At the same time, citations in AI answers can send readers and build brand recognition. Some publishers block AI crawlers broadly while they negotiate licensing agreements. Others block training but allow search to stay visible. A few allow everything and focus on the traffic that citations bring.
Whatever you choose, measure the effect. Track referral traffic from AI assistants, watch your crawl logs, and revisit the decision as AI products and licensing markets change. Our guide to AI referral traffic explains how to see visits from assistants in analytics.
Whichever policy you choose, write it down in plain language for your team, including the date you set it and the reasons. That makes the next review faster and keeps rules from drifting as people change roles.
Google’s AI features are a special case
Google-Extended controls whether Google may use your content for its Gemini models and some grounding uses. It does not control Google Search, and Google’s AI Overviews and AI Mode are part of Search. To limit how your content appears in AI Overviews, you would need Search-level controls such as nosnippet, which also affect regular search snippets. Blocking Googlebot entirely removes you from Google Search. Our guide on how to appear in Google AI Overviews explains how those features choose sources.
How to check which AI crawlers visit your site
Look at your server logs or your CDN’s bot analytics and filter by the user agents in the table above. You will see which bots crawl, how often and which pages they request. This data helps you decide whether crawling is a real cost problem and which pages AI systems are most interested in. Remember that any bot can claim a well-known name, so verify important bots against published IP ranges where available.
Common mistakes when you block AI crawlers
- Blocking every bot with a wildcard rule, which also blocks search engines and removes the site from Google and Bing.
- Blocking only GPTBot and assuming ChatGPT can no longer see the site, when its search crawler and user fetcher are separate.
- Copying an old list of user agents from a blog post, which may include deprecated names and miss new ones.
- Forgetting subdomains, each of which needs its own robots.txt.
- Blocking AI crawlers by IP range so broadly that legitimate visitors or search engines get caught.
- Making the change without telling marketing, who then wonders why AI referral traffic dropped.
Most of these come from treating “AI” as one thing. Decide separately about training, search and user requests, and the right rules usually follow.
How to decide, step by step
- List what your site earns from: ads, subscriptions, product sales, leads or reputation.
- Check your logs to see which AI bots visit and how much load they create.
- Check your analytics for traffic from AI assistants and what it converts to.
- Decide whether you want your content used for training, and set the training crawler rules to match.
- Decide whether you want to appear in AI answers, and set the search and user crawler rules to match.
- Add firewall rules only for bots that ignore robots.txt or crawl too aggressively.
- Review the results after a few months and adjust.
Following these steps keeps the choice to block AI crawlers tied to your business model rather than to headlines about AI.
Keeping your robots.txt up to date
New AI crawlers appear regularly, and companies rename or split existing ones. Review your robots.txt every few months, compare it with each company’s current documentation, and check your logs for unfamiliar bots. Keep a comment in the file explaining your policy, so the next person who edits it understands why each rule exists. If your site has an llms.txt file, keep it consistent with your robots.txt choices. Our guide on what llms.txt is explains that file.
FAQ: how to block AI crawlers
How do I block AI crawlers from my website?
Add Disallow rules for each AI user agent in your robots.txt file, and use firewall or CDN bot management for bots that ignore robots.txt.
Will blocking GPTBot remove me from ChatGPT?
Blocking GPTBot opts you out of training. ChatGPT search uses OAI-SearchBot, so block that too only if you want to leave ChatGPT search results.
Does blocking Google-Extended affect Google Search?
No. Google-Extended controls use in Gemini models and some grounding. Google Search, including AI Overviews, follows Googlebot rules.
Do all AI crawlers respect robots.txt?
Major companies say their crawlers do, though user-triggered fetchers can be treated differently. Some smaller or unknown bots ignore it, which is why firewall rules exist.
Should a business block AI crawlers?
Most businesses that want customers to find them should allow AI search crawlers and user fetchers. Blocking training crawlers is a separate choice with less impact on visibility.
How often should I update my AI crawler rules?
Review them every few months, since AI companies add and rename crawlers regularly.
Can I block AI crawlers from only part of my site?
Yes. Use a path in the Disallow rule, such as a members area or a folder of premium reports, and leave the rest of the site open. Remember that robots.txt is public, so it reveals which paths you consider sensitive.
Will blocking AI crawlers reduce my server costs?
It can, if AI bots make up a large share of your crawl traffic. Check your logs first. For many small sites, AI crawling is modest and the visibility tradeoff matters more than the bandwidth.
Does blocking AI crawlers remove my content from existing models?
No. Robots.txt affects future crawling. Content collected before you added rules may already be part of earlier training data, and companies handle removal requests through their own processes.
Do I need to tell anyone before I block AI crawlers?
There is no requirement, but tell your marketing, SEO and content teams. Changes to crawler access can shift traffic from AI assistants, and the people watching those numbers should know why.
Is there a standard file for AI permissions beyond robots.txt?
Robots.txt remains the main signal most AI companies follow. Some sites also publish an llms.txt file to guide AI tools toward useful content, and industry groups continue to discuss new standards for AI usage preferences.
Want to see where your customers are already asking? Get a free Reddit Opportunity Report showing which Reddit threads already rank for your keywords.